Patchright vs Camoufox
In this small, headless, no-proxy test, Patchright returned usable content faster and used less memory. Both tools received a 403 from G2. The Amazon difference happened once; it does not prove Patchright beats Camoufox at bypassing blocks.
One page at a time
Each cell is one fresh browser on the same target and network. “Likely usable” means the page was HTTP 200, had at least 500 visible characters, included the listed marker, and lacked known block markers.
Wikipedia article
Required text: web scraping
Amazon laptop search
Required text: laptop
Three browsers at once
One fresh browser for each of Wikipedia, Amazon, and G2 ran concurrently. Peak PSS is the sampled total for the Python workers and their browser process trees—not memory per tab or an exact hardware maximum.
2/3 likely usable · 3.79 s total · 815 MB peak PSS · 10.3 s sampled CPU
1/3 likely usable · 9.74 s total · 1514 MB peak PSS · 32.6 s sampled CPU
Open each attempt
These are the saved response metadata and screenshots for the corrected run. The raw HTML remains in the local lab; it is not in the public download.
Single browser: Wikipedia article
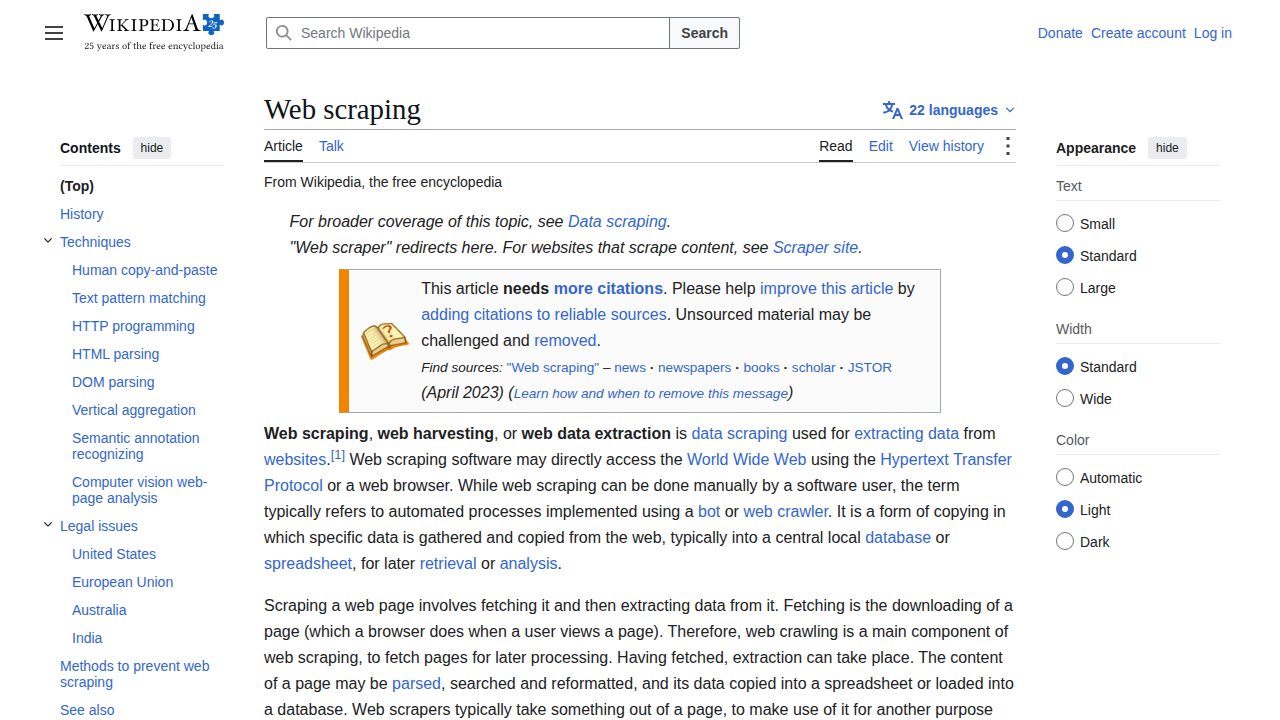
Patchright · Wikipedia article · HTTP 200 · likely usable
- Started
- 2026-09-28T21:21:16Z UTC
- URL
- https://en.wikipedia.org/wiki/Web_scraping
- Final URL
- https://en.wikipedia.org/wiki/Web_scraping
- Title
- Web scraping - Wikipedia
- HTTP status
- 200
- Visible text
- 28,674 characters
- HTML
- 417,239 bytes captured locally
- Browser
- 153.0.8010.12
- Page time
- 2.00 s
- Check
- likely usable
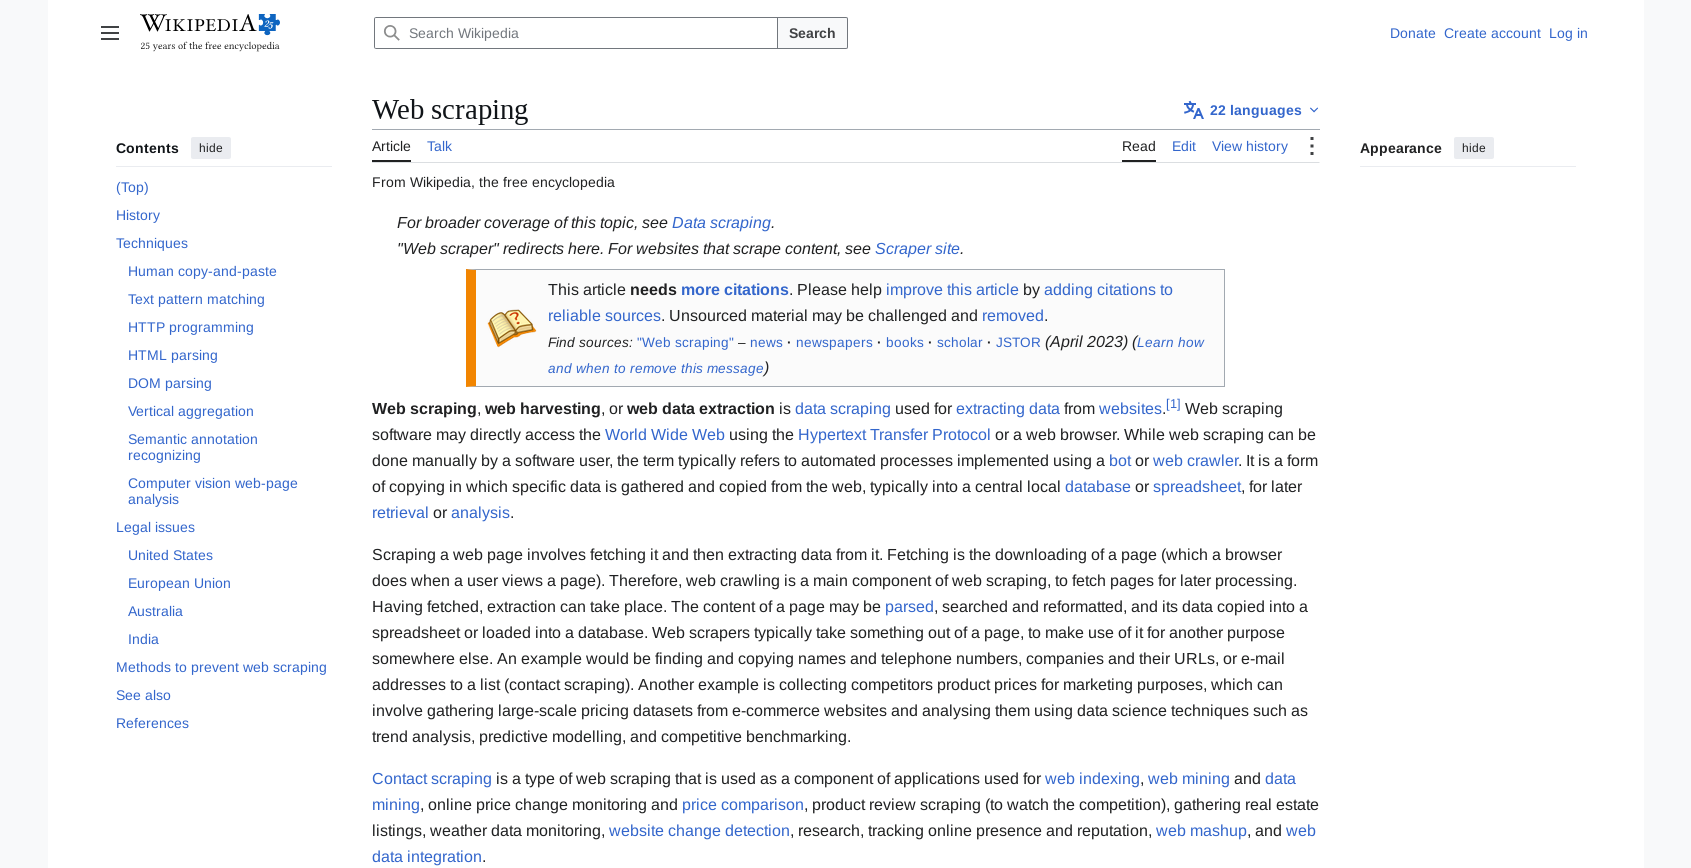
Camoufox · Wikipedia article · HTTP 200 · likely usable
- Started
- 2026-09-28T21:21:18Z UTC
- URL
- https://en.wikipedia.org/wiki/Web_scraping
- Final URL
- https://en.wikipedia.org/wiki/Web_scraping
- Title
- Web scraping - Wikipedia
- HTTP status
- 200
- Visible text
- 28,589 characters
- HTML
- 256,741 bytes captured locally
- Browser
- 152.0.4-beta.31
- Page time
- 7.05 s
- Check
- likely usable
Single browser: Amazon laptop search
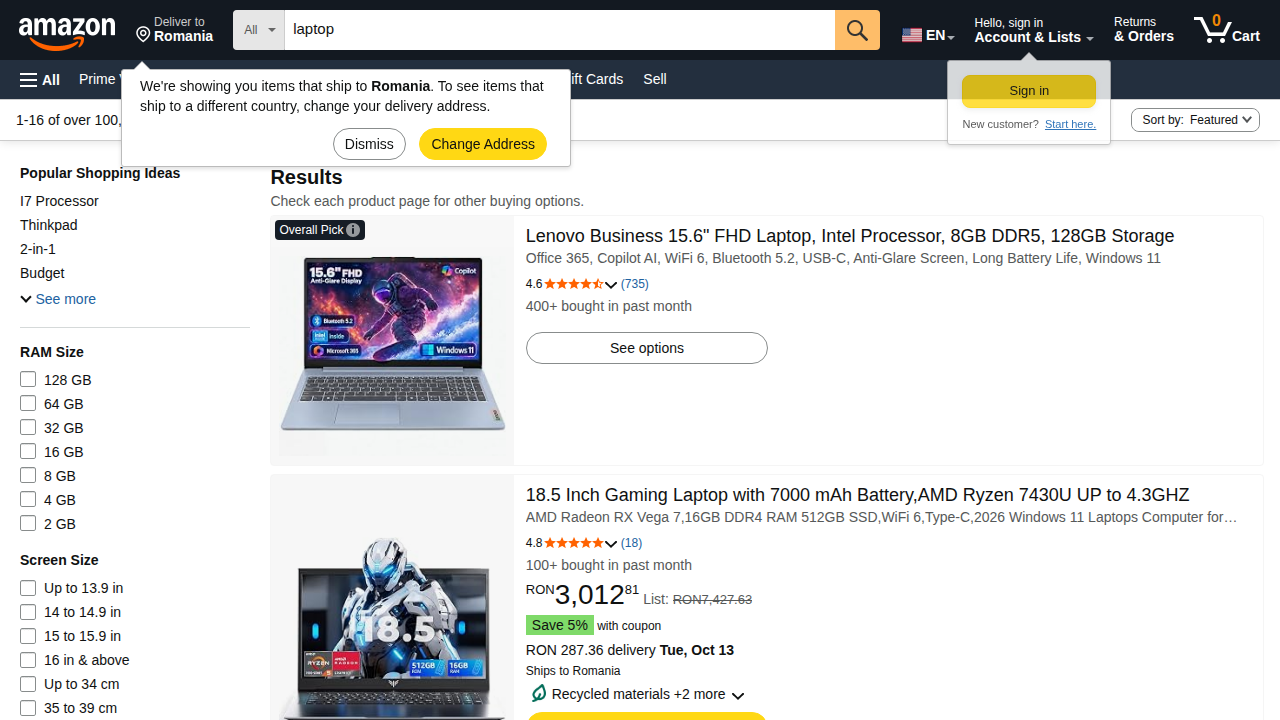
Patchright · Amazon laptop search · HTTP 200 · likely usable
- Started
- 2026-09-28T21:21:26Z UTC
- URL
- https://www.amazon.com/s?k=laptop
- Final URL
- https://www.amazon.com/s?k=laptop
- Title
- Amazon.com : laptop
- HTTP status
- 200
- Visible text
- 11,751 characters
- HTML
- 1,110,565 bytes captured locally
- Browser
- 153.0.8010.12
- Page time
- 2.65 s
- Check
- likely usable
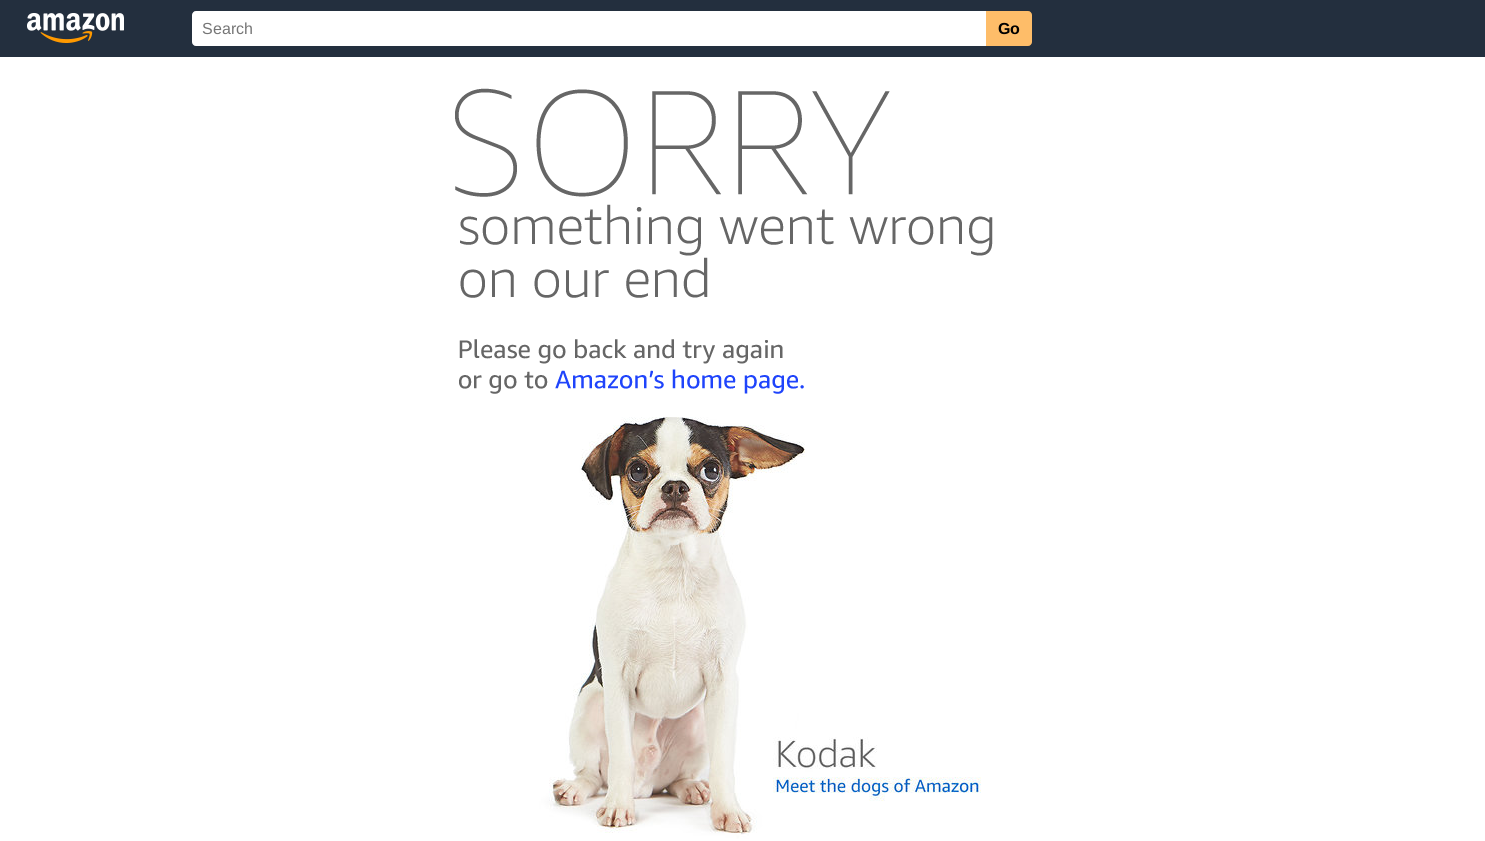
Camoufox · Amazon laptop search · HTTP 503 · http error
- Started
- 2026-09-28T21:21:28Z UTC
- URL
- https://www.amazon.com/s?k=laptop
- Final URL
- https://www.amazon.com/s?k=laptop
- Title
- Sorry! Something went wrong!
- HTTP status
- 503
- Visible text
- 0 characters
- HTML
- 2,344 bytes captured locally
- Browser
- 152.0.4-beta.31
- Page time
- 3.67 s
- Check
- http error
Single browser: G2 Asana reviews
Patchright · G2 Asana reviews · HTTP 403 · http error
- Started
- 2026-09-28T21:21:32Z UTC
- URL
- https://www.g2.com/products/asana/reviews
- Final URL
- https://www.g2.com/products/asana/reviews
- Title
- g2.com
- HTTP status
- 403
- Visible text
- 0 characters
- HTML
- 2,619 bytes captured locally
- Browser
- 153.0.8010.12
- Page time
- 1.28 s
- Check
- http error
Camoufox · G2 Asana reviews · HTTP 403 · http error
- Started
- 2026-09-28T21:21:34Z UTC
- URL
- https://www.g2.com/products/asana/reviews
- Final URL
- https://www.g2.com/products/asana/reviews
- Title
- g2.com
- HTTP status
- 403
- Visible text
- 0 characters
- HTML
- 2,563 bytes captured locally
- Browser
- 152.0.4-beta.31
- Page time
- 6.78 s
- Check
- http error
Three concurrent browsers
Patchright · Wikipedia article · HTTP 200 · likely usable
- Started
- 2026-09-28T21:21:41Z UTC
- URL
- https://en.wikipedia.org/wiki/Web_scraping
- Final URL
- https://en.wikipedia.org/wiki/Web_scraping
- Title
- Web scraping - Wikipedia
- HTTP status
- 200
- Visible text
- 28,674 characters
- HTML
- 417,239 bytes captured locally
- Browser
- 153.0.8010.12
- Page time
- 2.45 s
- Check
- likely usable
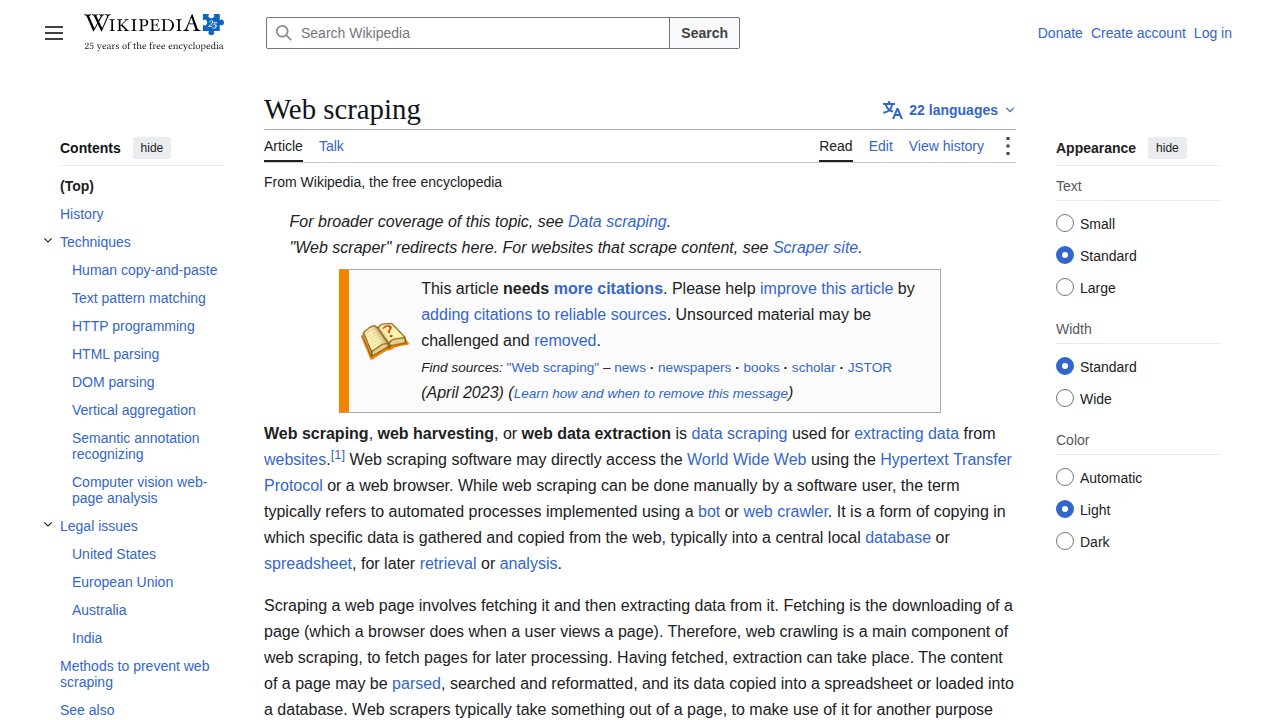
Patchright · Amazon laptop search · HTTP 200 · likely usable
- Started
- 2026-09-28T21:21:41Z UTC
- URL
- https://www.amazon.com/s?k=laptop
- Final URL
- https://www.amazon.com/s?k=laptop
- Title
- Amazon.com : laptop
- HTTP status
- 200
- Visible text
- 11,899 characters
- HTML
- 1,107,298 bytes captured locally
- Browser
- 153.0.8010.12
- Page time
- 3.44 s
- Check
- likely usable
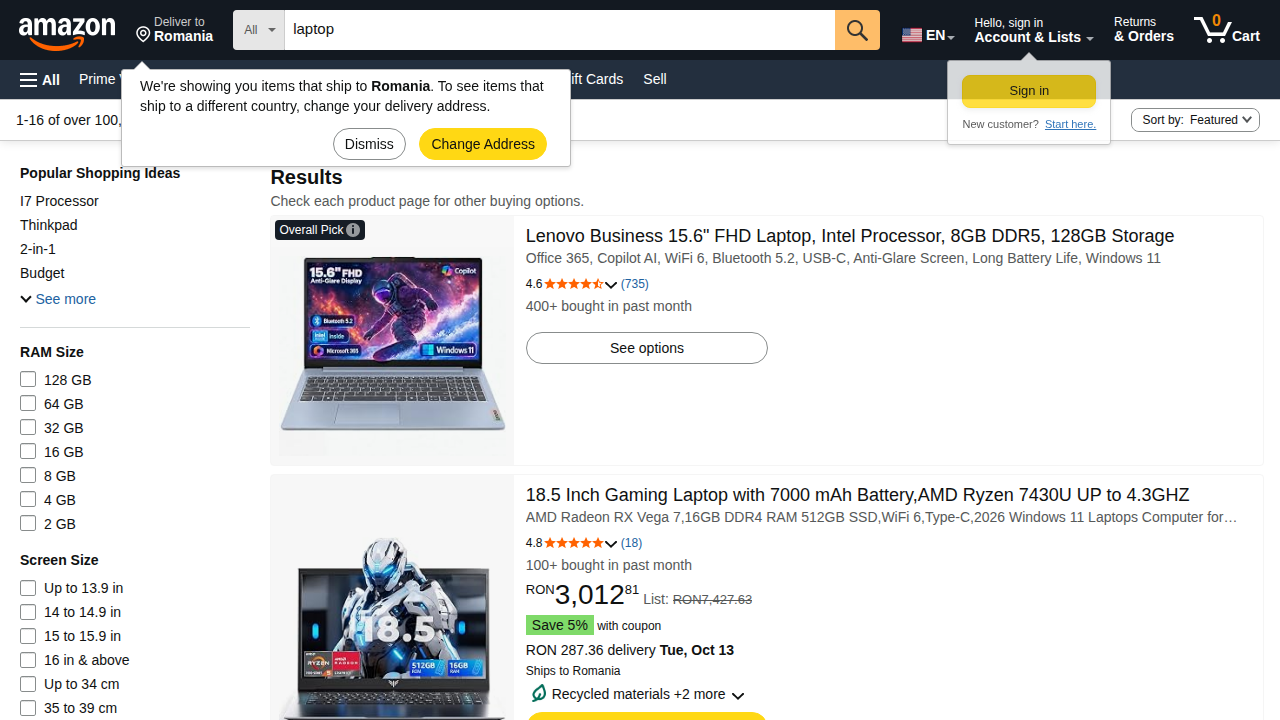
Patchright · G2 Asana reviews · HTTP 403 · http error
- Started
- 2026-09-28T21:21:41Z UTC
- URL
- https://www.g2.com/products/asana/reviews
- Final URL
- https://www.g2.com/products/asana/reviews
- Title
- g2.com
- HTTP status
- 403
- Visible text
- 0 characters
- HTML
- 2,619 bytes captured locally
- Browser
- 153.0.8010.12
- Page time
- 1.93 s
- Check
- http error
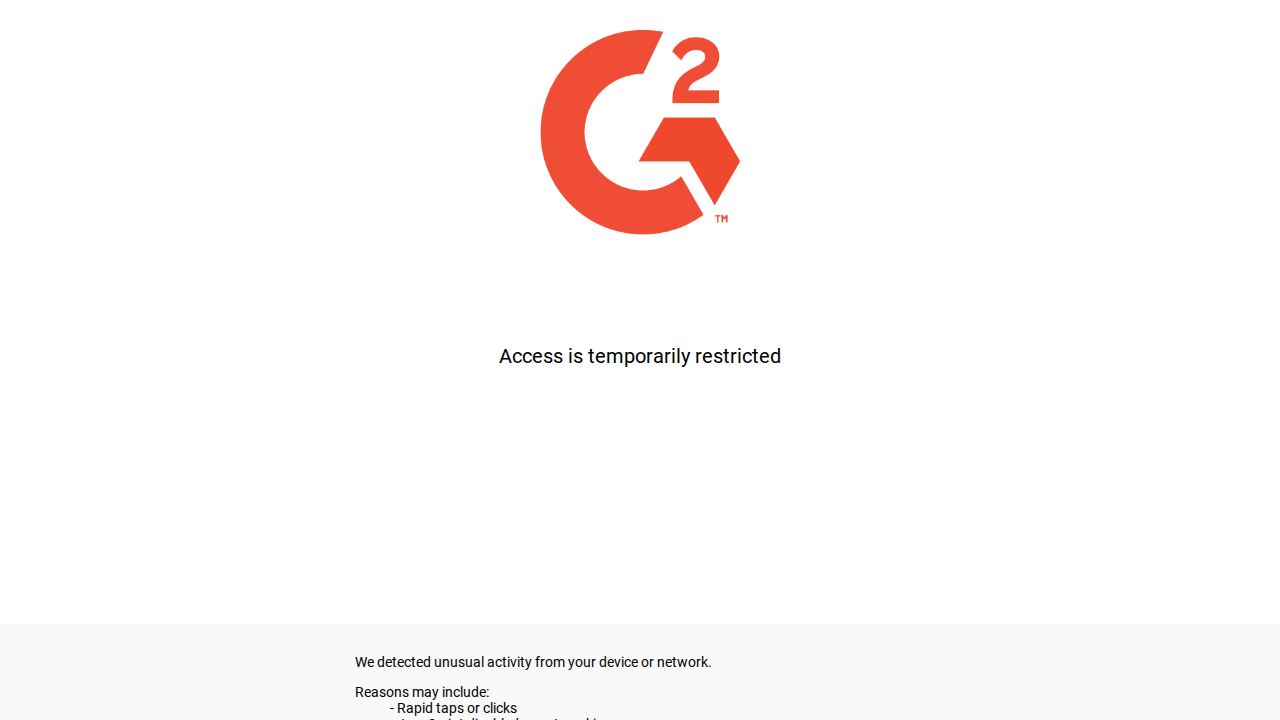
Camoufox · Wikipedia article · HTTP 200 · likely usable
- Started
- 2026-09-28T21:21:45Z UTC
- URL
- https://en.wikipedia.org/wiki/Web_scraping
- Final URL
- https://en.wikipedia.org/wiki/Web_scraping
- Title
- Web scraping - Wikipedia
- HTTP status
- 200
- Visible text
- 28,589 characters
- HTML
- 256,938 bytes captured locally
- Browser
- 152.0.4-beta.31
- Page time
- 8.28 s
- Check
- likely usable
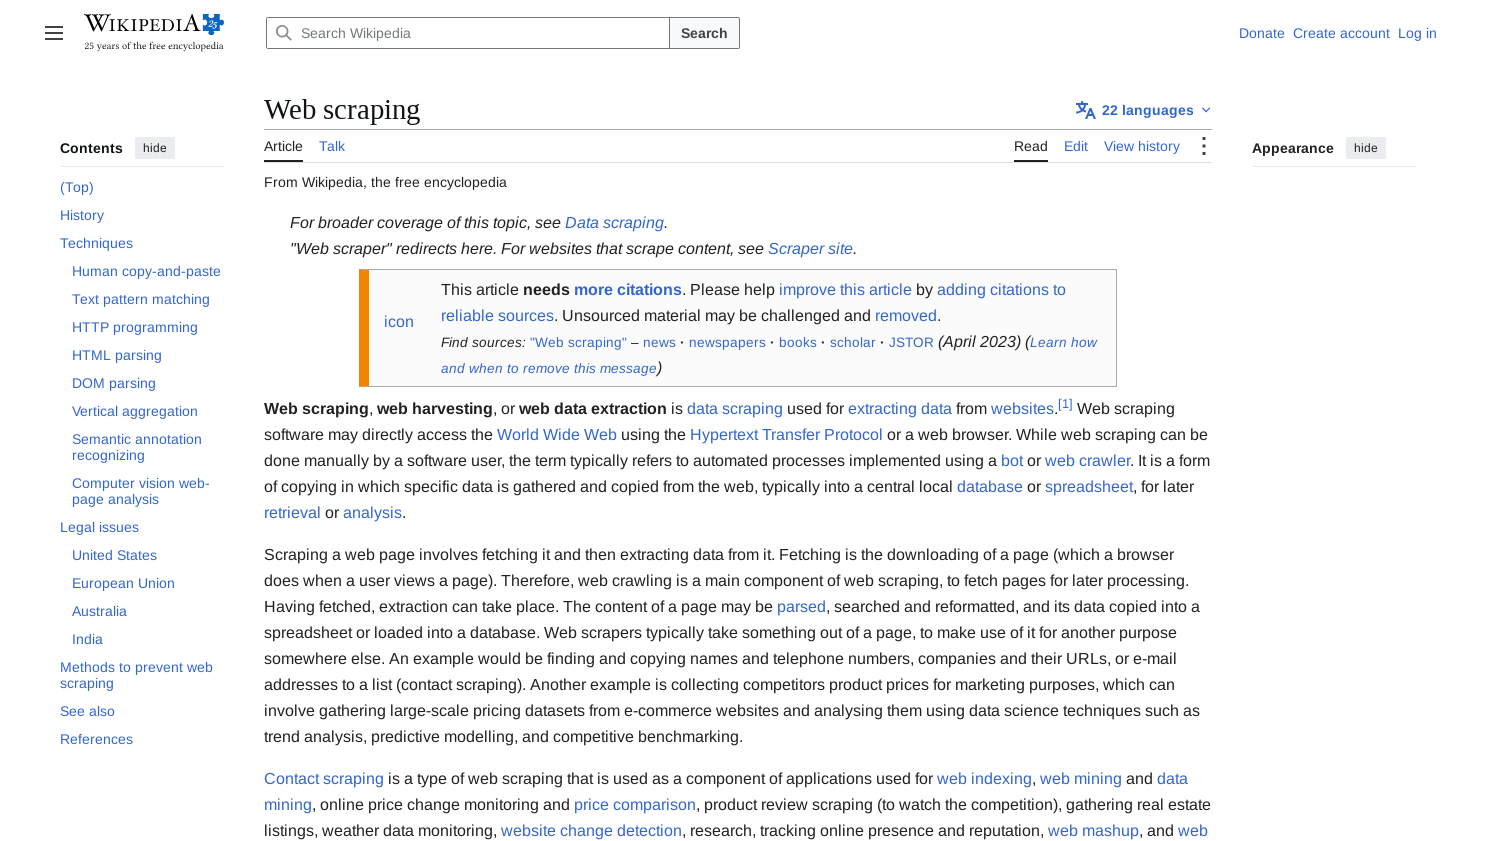
Camoufox · Amazon laptop search · HTTP 503 · http error
- Started
- 2026-09-28T21:21:45Z UTC
- URL
- https://www.amazon.com/s?k=laptop
- Final URL
- https://www.amazon.com/s?k=laptop
- Title
- Sorry! Something went wrong!
- HTTP status
- 503
- Visible text
- 0 characters
- HTML
- 2,344 bytes captured locally
- Browser
- 152.0.4-beta.31
- Page time
- 5.87 s
- Check
- http error
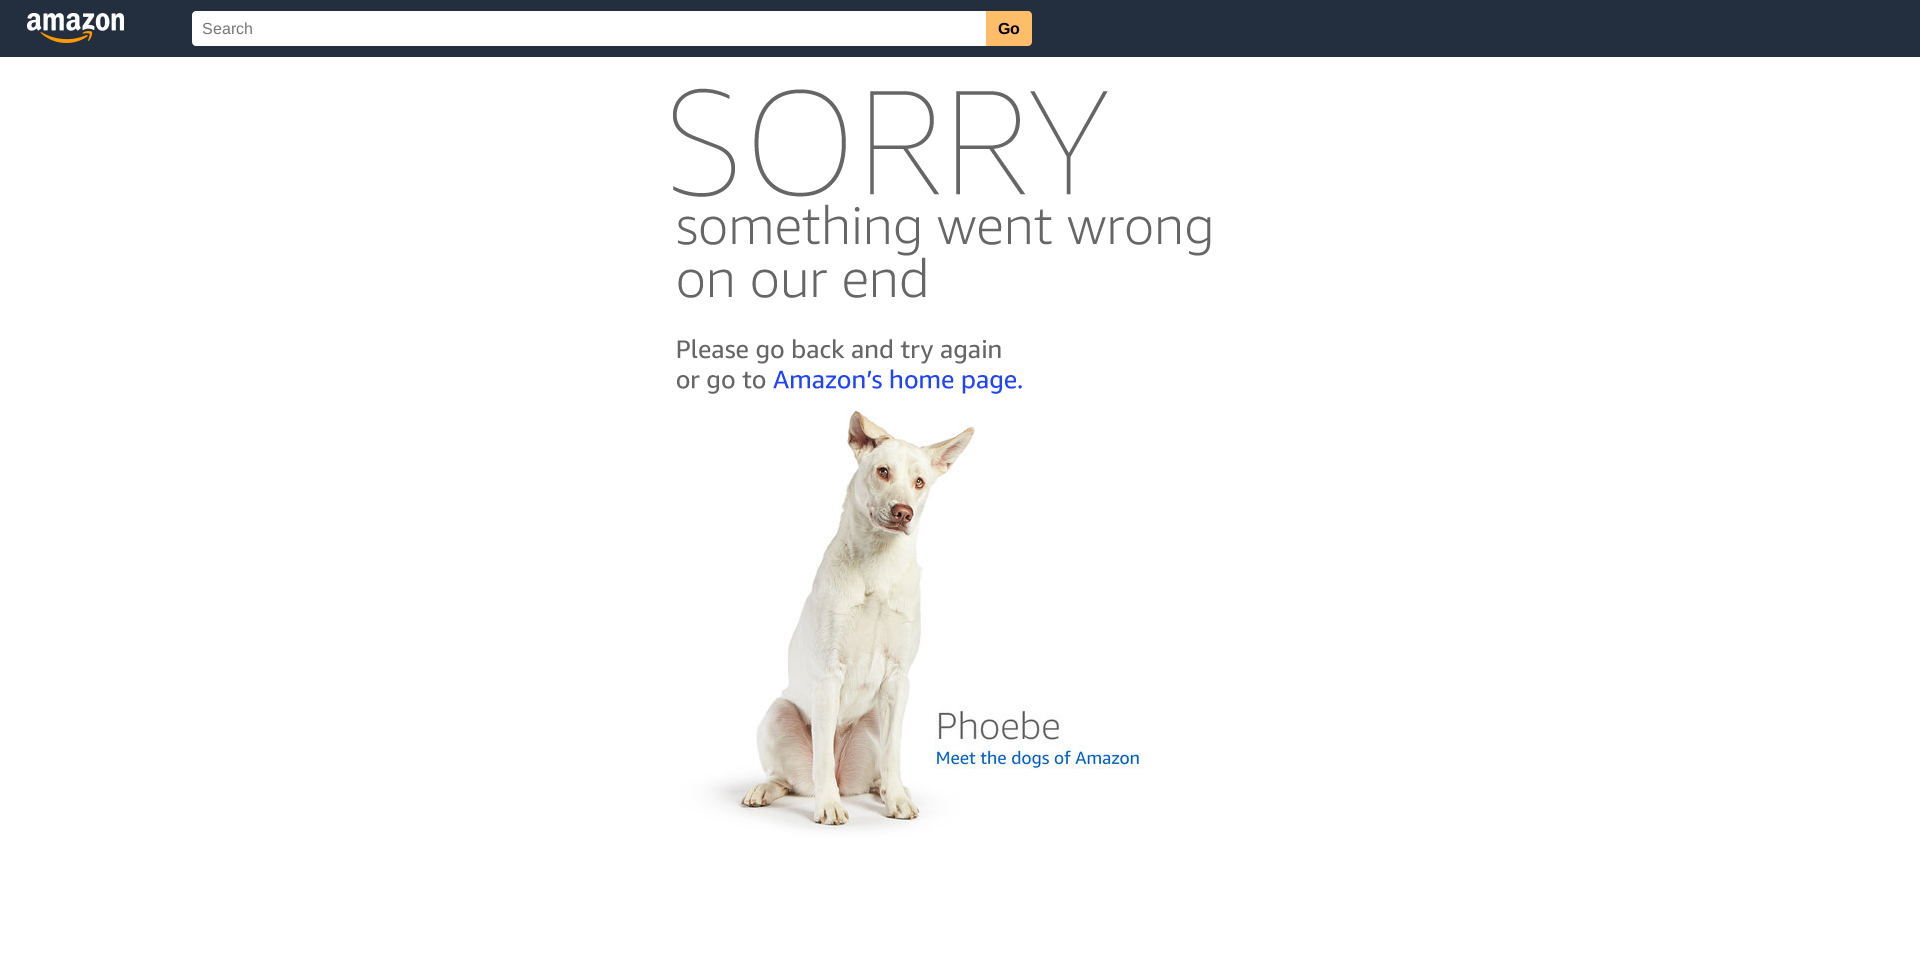
Camoufox · G2 Asana reviews · HTTP 403 · http error
- Started
- 2026-09-28T21:21:45Z UTC
- URL
- https://www.g2.com/products/asana/reviews
- Final URL
- https://www.g2.com/products/asana/reviews
- Title
- g2.com
- HTTP status
- 403
- Visible text
- 0 characters
- HTML
- 2,563 bytes captured locally
- Browser
- 152.0.4-beta.31
- Page time
- 9.51 s
- Check
- http error
Try one URL yourself
These small examples fetch a Wikipedia page and print readable text, with an error for a missing response, non-200 status, or empty body. They are starting examples, not the resource-measurement script above. For a real job, check the fields you need and add a fallback separately.
Patchright
python -m venv .venv
source .venv/bin/activate
pip install patchright==1.63.0
patchright install chromiumfrom patchright.sync_api import sync_playwright
url = "https://en.wikipedia.org/wiki/Web_scraping"
with sync_playwright() as p:
browser = p.chromium.launch(headless=True)
try:
page = browser.new_page()
response = page.goto(url, wait_until="domcontentloaded", timeout=30000)
if response is None or response.status != 200:
raise RuntimeError(f"Fetch failed: HTTP {response.status if response else 'no response'}")
text = page.locator("body").inner_text(timeout=5000)
if len(text.strip()) < 100:
raise RuntimeError("Page returned too little readable content")
print(text)
finally:
browser.close()Camoufox
python -m venv .venv
source .venv/bin/activate
pip install camoufox==0.5.6
python -m camoufox fetchfrom camoufox.sync_api import Camoufox
url = "https://en.wikipedia.org/wiki/Web_scraping"
with Camoufox(headless=True) as browser:
page = browser.new_page()
response = page.goto(url, wait_until="domcontentloaded", timeout=30000)
if response is None or response.status != 200:
raise RuntimeError(f"Fetch failed: HTTP {response.status if response else 'no response'}")
text = page.locator("body").inner_text(timeout=5000)
if len(text.strip()) < 100:
raise RuntimeError("Page returned too little readable content")
print(text)Add your proxy
Add import os and pass this option when launching either browser. This proxy setup was not used in the measured run. Keep one IP through a browser session.
# Optional: set these from your environment, never in source control.
proxy = {
    "server": os.environ["PROXY_SERVER"],  # e.g. http://host:port
    "username": os.environ["PROXY_USER"],
    "password": os.environ["PROXY_PASSWORD"],
}
# Patchright: p.chromium.launch(headless=True, proxy=proxy)
# Camoufox: Camoufox(headless=True, proxy=proxy)
Install and proxy syntax checked against the Patchright repository and Camoufox documentation. Browser downloads may change after this test; the recorded browser versions above are what we measured.
What this does not prove
- There was only one corrected attempt per target and one concurrent group. Site defenses and network conditions change.
- An earlier Camoufox Amazon screenshot showed products after the first, too-early text check. We discarded that classification. The corrected run got HTTP 503, which may be transient or server-side.
- “Likely usable” checks general page text, not a product price or another job-specific required field.
- No proxy cost, bandwidth, or residential-proxy success rate was measured here.
- Run three paired repeats and a same-proxy track before choosing either tool for a valuable scraping job.